Why I build fair test plans to rank [Product]s
I show a simple step by step method to build fair, repeatable test plans that reduce bias and reveal real differences between [Product]s, so I can make confident, defensible rankings I can explain and repeat with clear data and notes.
What I need before I start
I need a list of candidate [Product]s, a consistent test environment, basic analytics tools, clear KPIs, time for trials, and commitment to objectivity.

Plan a Fair Test: Clear Steps for Accurate Results
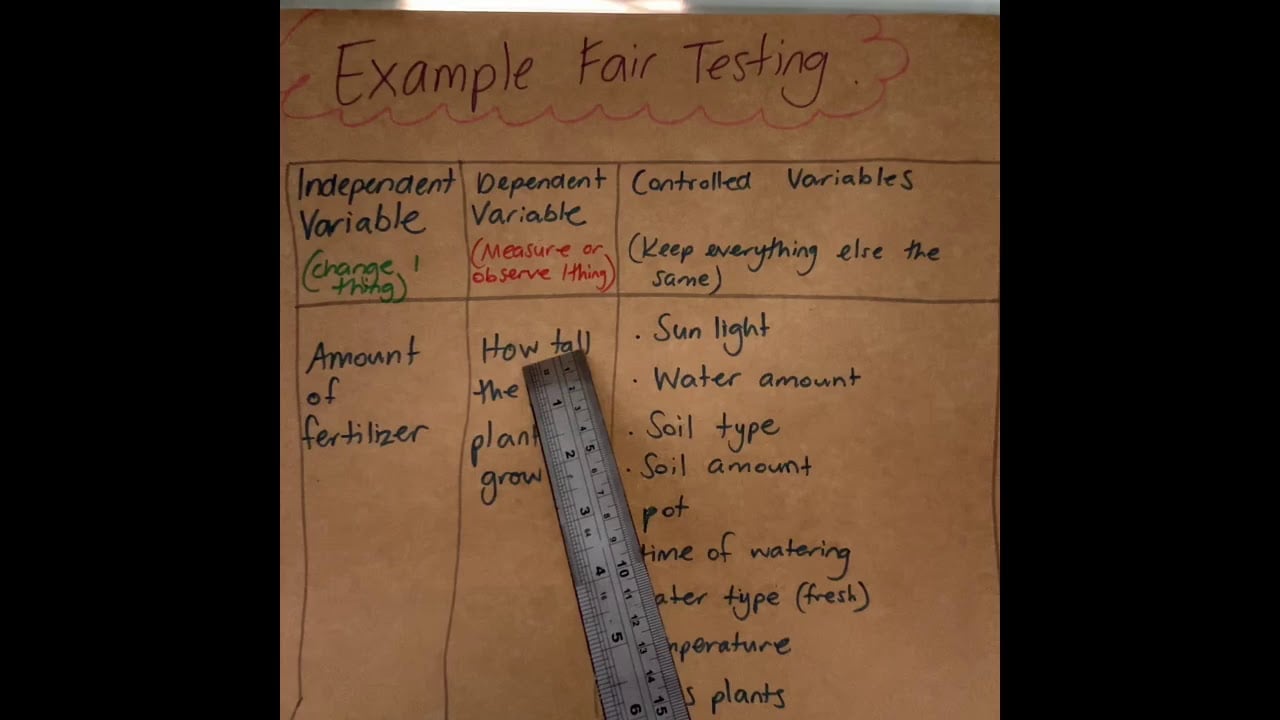
Step 1 — Clarify what 'fair' means for my [Product] ranking
What if fairness isn't just about numbers? (Spoiler: it rarely is.)Define the goal and scope: am I ranking for user preference, performance, value, or a blend? I state my audience, constraints, and the hypotheses I want to test.
Write down concrete examples to anchor choices (e.g., ranking earbuds for commuter noise reduction and price; hypothesis: ANC improves commute satisfaction by ≥15%). Decide what counts as a meaningful difference—my minimum effect size.
List explicit inclusion/exclusion rules and tie-breakers so every candidate is judged on the same footing.
Preregister the objectives, primary and secondary outcomes, and minimum effects that matter. Note known biases (brand familiarity, review samples) and state mitigation steps (blinding, randomization). I begin by defining the goal and scope: am I ranking for user preference, performance, value, or a blend? I state my audience, constraints, and the hypotheses I want to test. I list explicit inclusion/exclusion rules so every candidate is judged on the same footing. I decide what constitutes a tie and how I’ll break it. To avoid post-hoc rationalization, I preregister the objectives, primary and secondary outcomes, and minimum effects that matter. I also note any known biases (e.g., brand familiarity) and how I’ll mitigate them. This upfront clarity keeps me honest and makes my final ranking defensible.

Step 2 — Choose the right metrics and KPIs to reveal real differences
Which metric actually tells the truth — revenue, speed, or my gut? Hint: I picked measurable winners.Pick one primary metric that maps directly to my goal. I choose something measurable like task completion rate, time-to-value, or cost per outcome and state why it matters for this ranking.
Select a few secondary metrics to add context and catch trade-offs.
Estimate the minimum detectable effect (MDE) I care about and calculate required sample sizes (use 80% power, α=0.05 or a justified alternative). I use online power/sample-size calculators or simple formulas so I’m not chasing noise.
Decide how I’ll combine metrics: pick a weighted score or composite index and justify weights (example: 70% primary / 20% reliability / 10% price) and preregister them.
Prefer blinded measurements and automated capture (logs, scripts, video timestamps) to minimize subjective bias and disputes about what the numbers actually mean.

Step 3 — Design unbiased tests: controls, variables, and sampling
Surprising benefit: small, well-designed tests beat sloppy big ones — want proof?Define the control condition and one clear variable at a time. I keep one baseline product/configuration and change only the factor I’m testing (example: feature A on vs off).
Specify the variables I’ll measure and how I’ll manipulate them. I document exact settings (e.g., network throttling at 3 Mbps, battery at 20%, locale=en-US).
Randomize or block exposures to control confounders. I randomize users to products or block by device type, region, or experience level so comparisons are balanced.
Create repeatable protocols and scripts. I list environment specs, device models (e.g., Pixel 4, iPhone 12), and step-by-step scripts testers follow so every trial runs identically.
Set sampling frames and quotas. I define audience sources (lab recruits, panel, in-market users) and quotas (age, OS, geography) so each product sees comparable cohorts.
Document blinding and operational runbook.
I set blinding rules so reviewers don’t know which product they’re evaluating when possible. I also set a runbook that covers test duration, stopping rules, and how I’ll handle anomalies or failures. Thoughtful design prevents accidental bias and saves time when I execute.

Step 4 — Run, analyze, and defend my rankings with transparency
I show you how to turn messy results into confident rankings — and what to say when they surprise you.Log everything: I record timestamps, environment notes, run IDs, configuration snapshots, deviations, and raw outputs so every result is traceable.
Pre-specify transformations and cleaning rules before peeking: I document exclusions, imputation rules, and derived metrics (example: drop runs >3× median latency).
Run appropriate statistical tests: I choose tests that match the design (t-tests, nonparametric tests, mixed models), report confidence intervals and effect sizes, and assess practical importance, not just p-values.
Visualize distributions, not just averages: I use histograms, violin plots, and per-user lines to spot outliers and trade-offs (example: A has lower median but a heavier tail).
Document and publish methods: I keep a change log, publish sanitized raw data extracts, and provide reproducible scripts (R/Python notebooks).
Explain inconclusive results and propose follow-ups, then convert findings into a ranked list with clear justification and an archived audit record.

Wrap-up and next steps
I’ve given a compact, repeatable roadmap to build a fair test plan and defend the resulting rankings; next I’ll run a small pilot, refine where needed, then scale confidently—try this approach, share your findings, and let’s improve fair evaluation together.